Dovada checks the difference - automatically, on every ticket and every release - and shows exactly how it knows.
A test you've already shipped behind
This test exists. It runs. It passes.
it('sends an alert', () => {
  alertOnCallIfDead(deadDelivery)
  expect(sendAlert).toHaveBeenCalled()
})
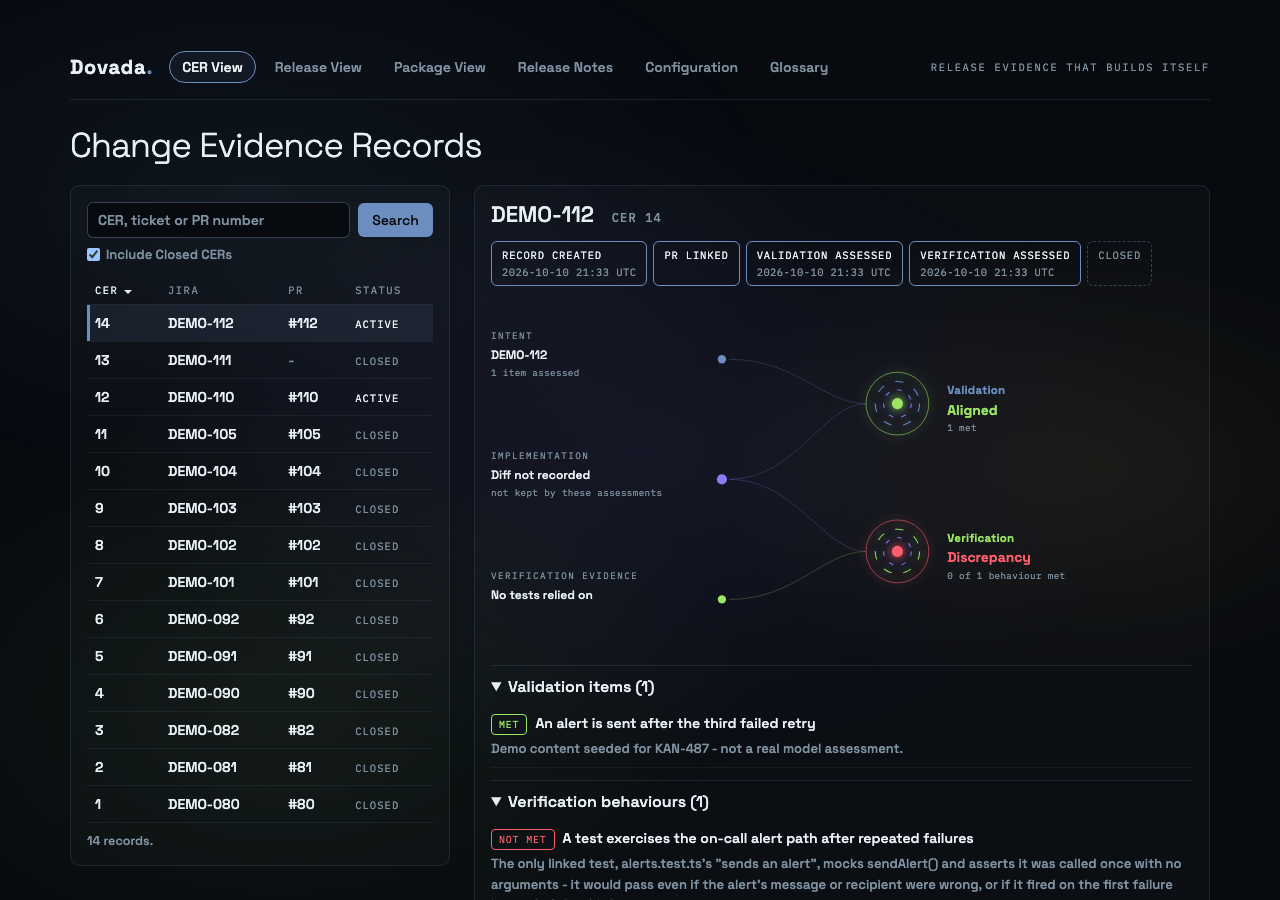
It doesn't check the alert's message, who it reaches, or whether it fired after the third failure instead of the first. Green in CI. Proves almost nothing.
Real code behind a real release - not a hypothetical. Dovada caught it. Next slide.
One record · DEMO-112
Same ticket. Two answers that disagree.
/dovada/cer/14
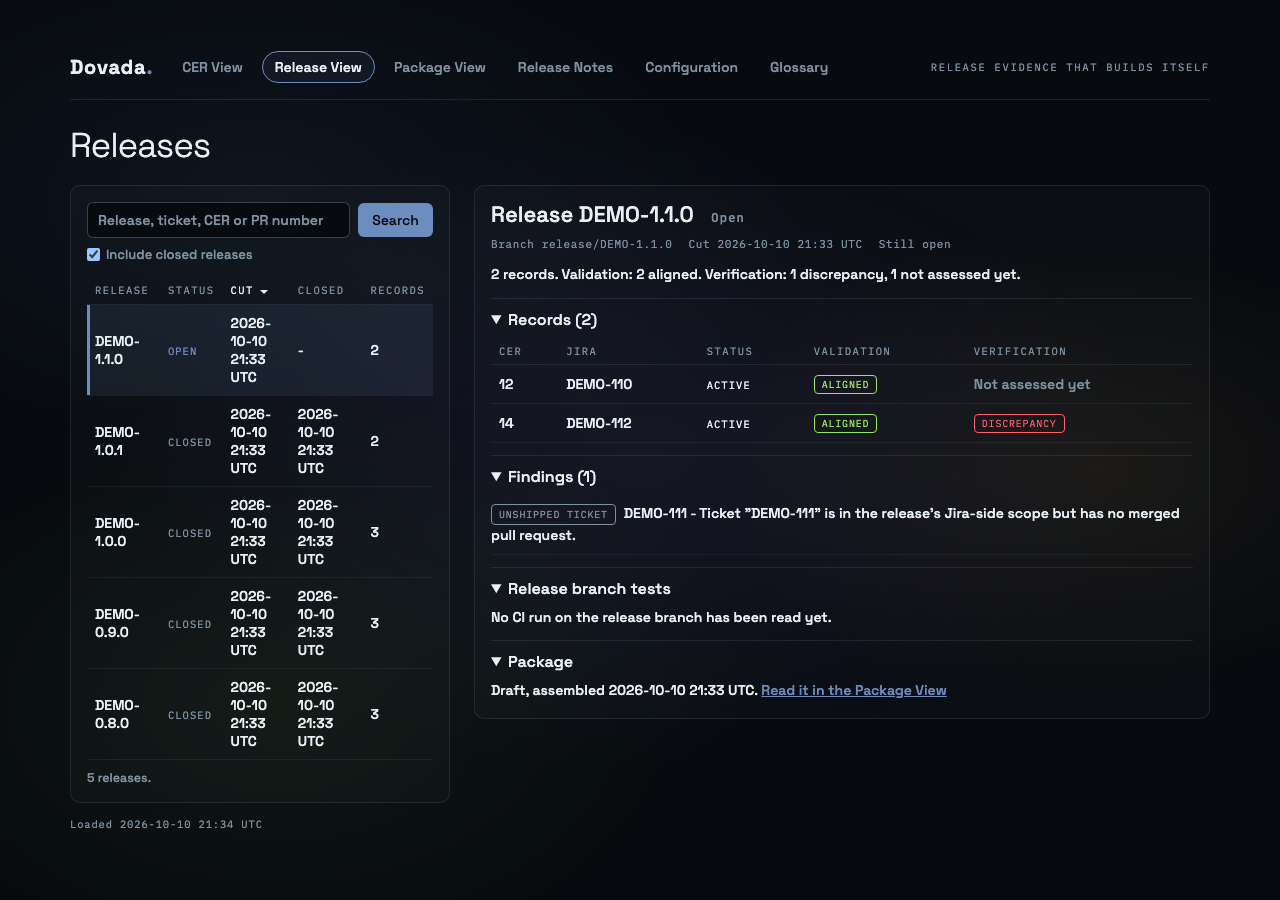
What summaries miss · DEMO-111
Done. Shipped. Except it wasn't.
/dovada/release/DEMO-1.1.0
How each answer gets made
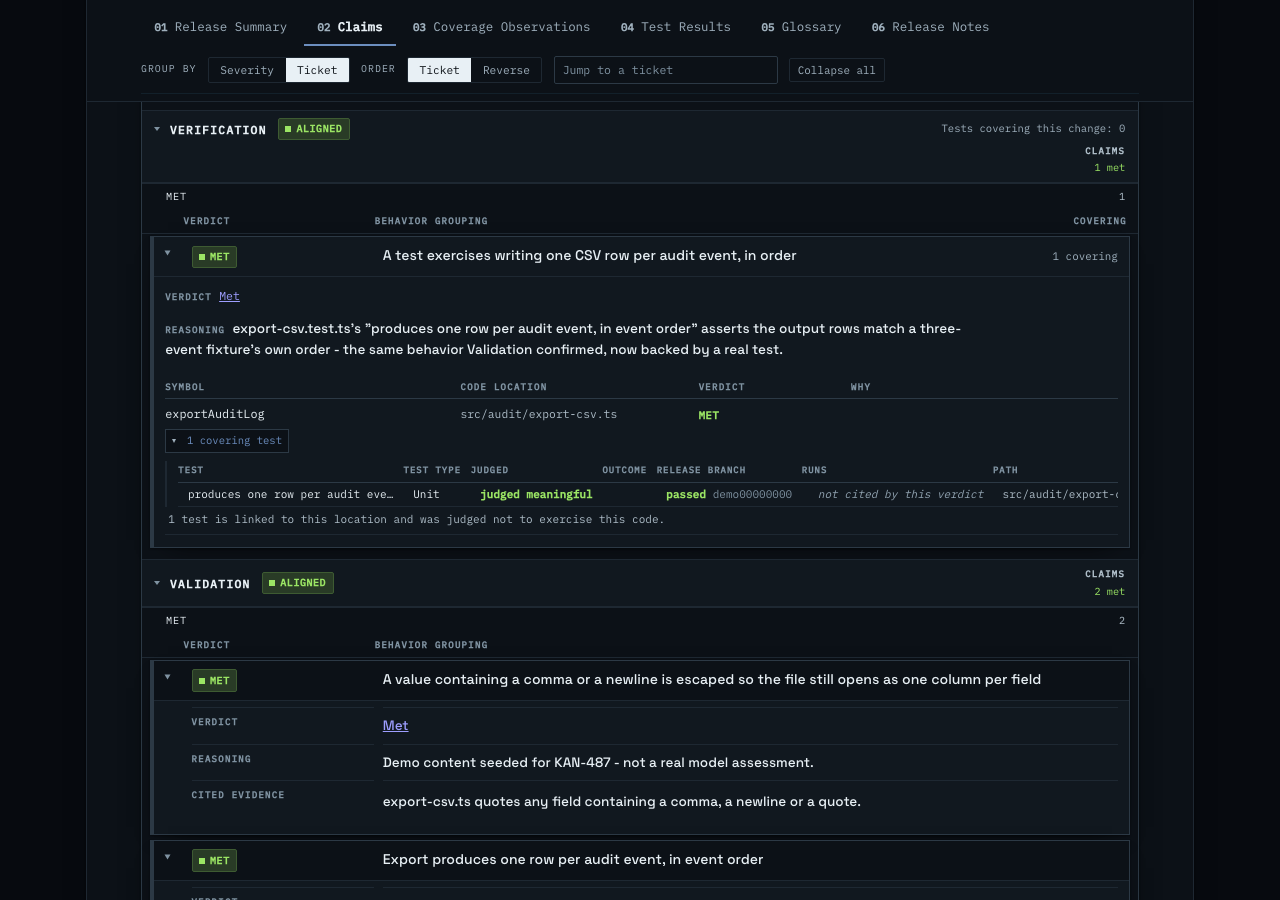
Two verticals, assessed separately
Validation
Did we build the right thing?
Every requirement a ticket states, read against the pull requests that claim to satisfy it - judged one requirement at a time, never rounded up into a single score.
Verification
Did we prove it works?
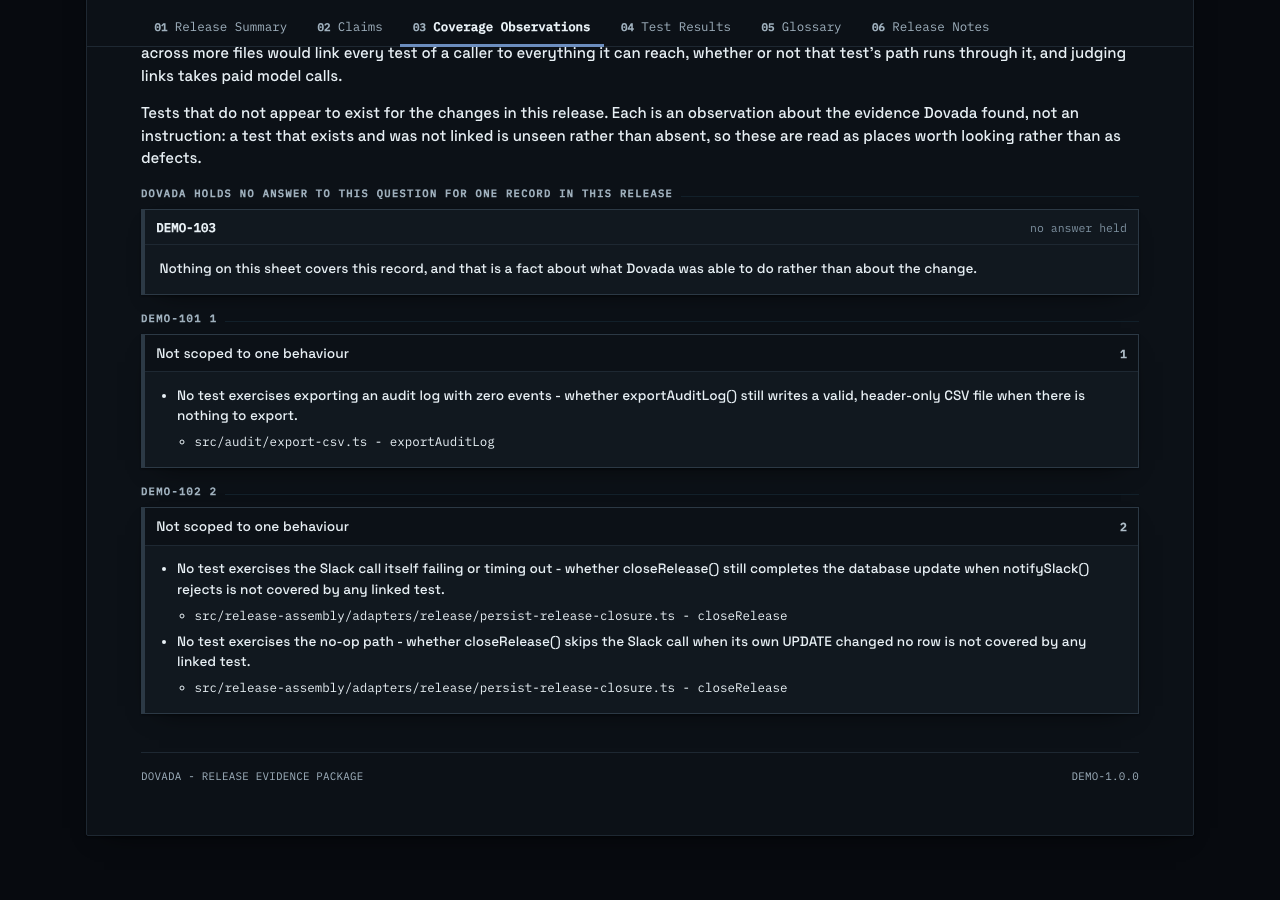
From the code that changed, traced through real imports and calls to the tests that actually exercise it - then judged for whether that link is meaningful, not just present.
Every "judged" above is a real Claude call, under your own Anthropic account and contract - not Dovada's. Nothing proprietary to trust: the model, the spend and the audit trail are yours. Configured for Anthropic today; choice of provider is coming.